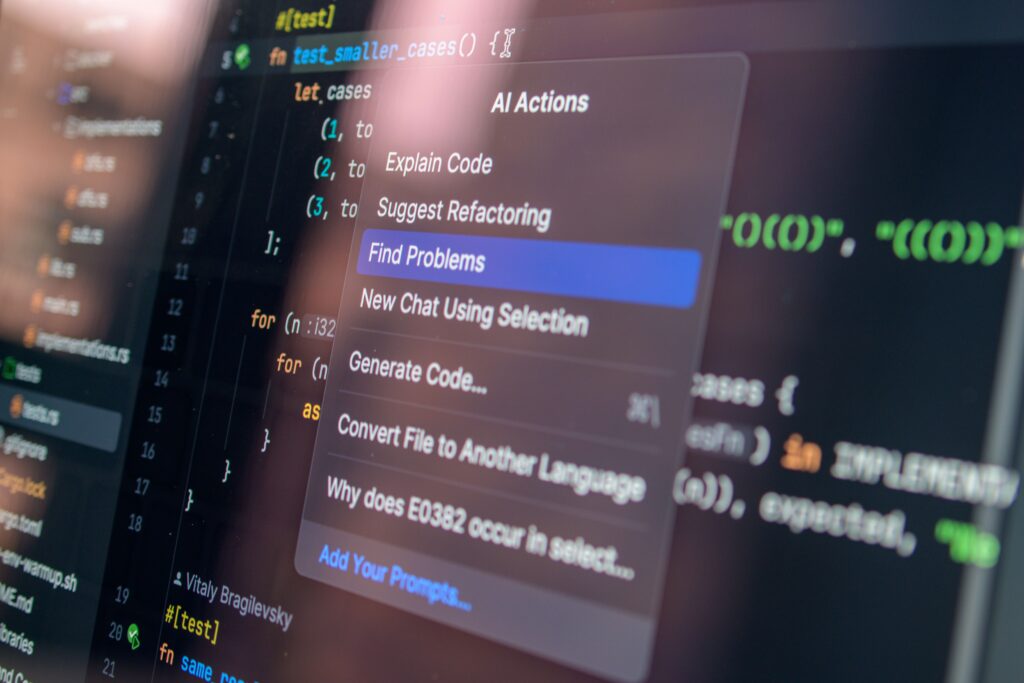

Recent discussions around automated development tools raise an important question: can coding agents truly be evaluated? While some software factory providers insist that AI-driven code generators defy traditional assessment, a shift in focus from AI behavior to the actual output makes evaluation not only possible but essential.
Evaluating AI agents requires us to rethink established software testing principles. Instead of judging the agent’s internal algorithms as a black box, we can apply proven quality gates—such as unit and integration tests—to the artifacts they produce. By treating AI-generated code like any other contribution, teams benefit from transparent metrics and continuous feedback loops.
In practical terms, a blend of static analysis, code review checklists, and performance benchmarks offers a comprehensive view of code health. Tools like sponsor-clickhouse can capture build logs and testing metrics at scale, while code coverage reports and maintainability scores reveal areas for improvement. This approach aligns with modern AI engineering best practices and ensures each pull request meets project standards.
From my perspective, the key lies in collaboration: pairing human expertise with automated agents creates a virtuous cycle of refinement. As coding agents produce drafts, developers guide them through targeted tests and style checks. Over time, this iterative model sharpens the tool’s outputs, accelerating delivery without compromising on quality or security.
In conclusion, coding agents deserve the same rigorous evaluation we apply to any software component. By focusing on tangible deliverables—whether through unit tests, performance dashboards, or peer reviews—we can harness AI’s potential responsibly. Ultimately, success hinges on treating AI-generated code as a first-class citizen in our quality assurance process.